Start from a monitor
HTTP, cron and browser monitors linked to a service can open incidents on failure and resolve them on recovery when the service creates incidents automatically.
Give every incident a clear timeline. Bring the signal, the response and the customer updates together, from the first alert to resolved.
Free tier included. No credit card required.
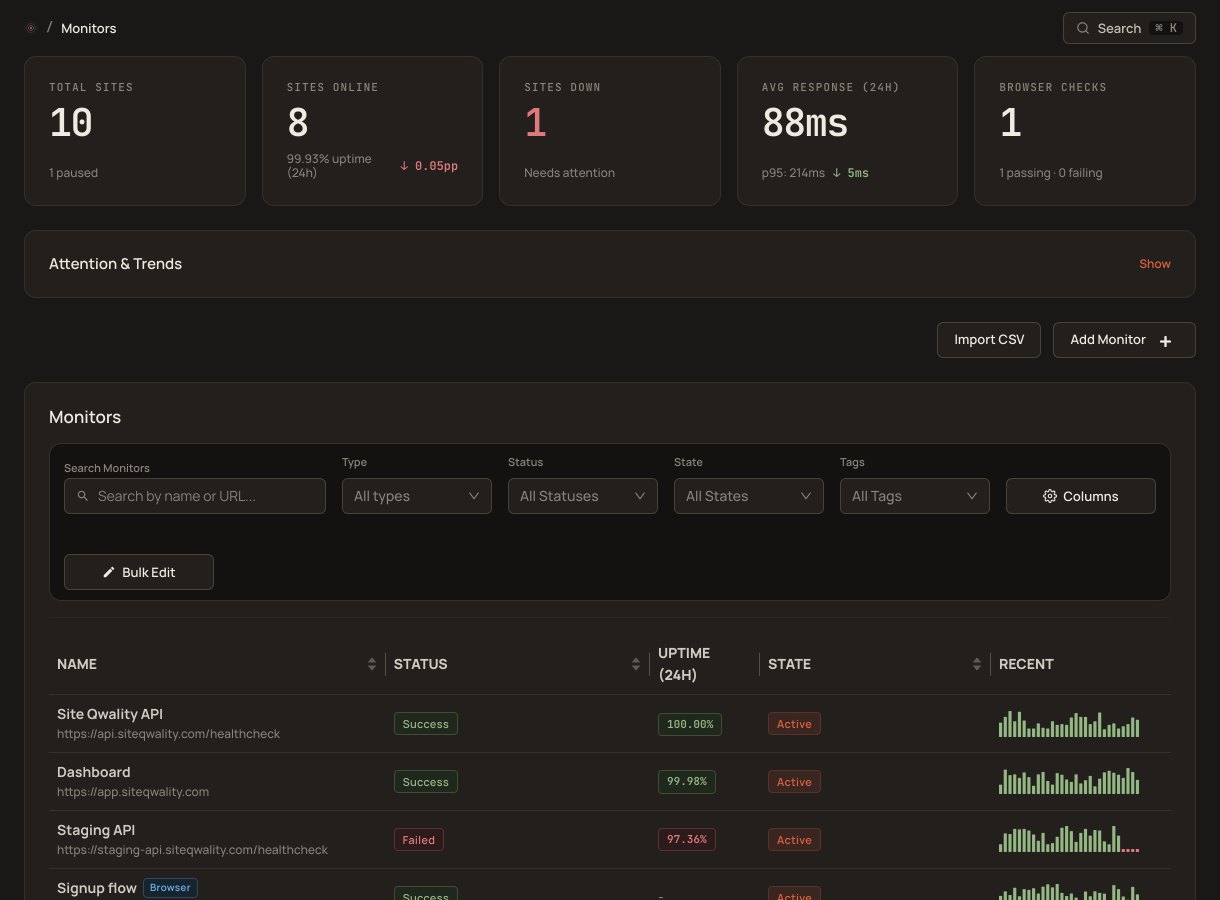
Keep the current state visible and the history intact. Everyone should be able to see what changed and where the investigation stands.
HTTP, cron and browser monitors linked to a service can open incidents on failure and resolve them on recovery when the service creates incidents automatically.
Move through investigating, identified, monitoring and resolved with timestamped updates and an explicit severity.
Link affected services and publish updates to your status page, so the response has a clear public home.
Follow an example incident from first report to recovery.
Create an incident around the affected service. Set its severity and record the first update so the team has a common starting point.
The first update records what is known, without implying a cause before it is identified.
Add updates as you identify the problem and apply a fix. Carry relevant updates onto your status page for customers following along.
Each update remains in the incident timeline.
Resolve the incident after recovery. Keep the timeline, severity and updates available for the next review or customer question.
The incident record keeps the investigation and recovery updates together.
Yes. HTTP, cron and browser monitors linked to a service can open incidents on failure and resolve them on recovery when the service creates incidents automatically.
Minor, major and critical. The incident lifecycle is investigating, identified, monitoring and resolved.
No. The timestamped incident timeline is retained, but structured postmortem templates and action-item tracking are not available today.